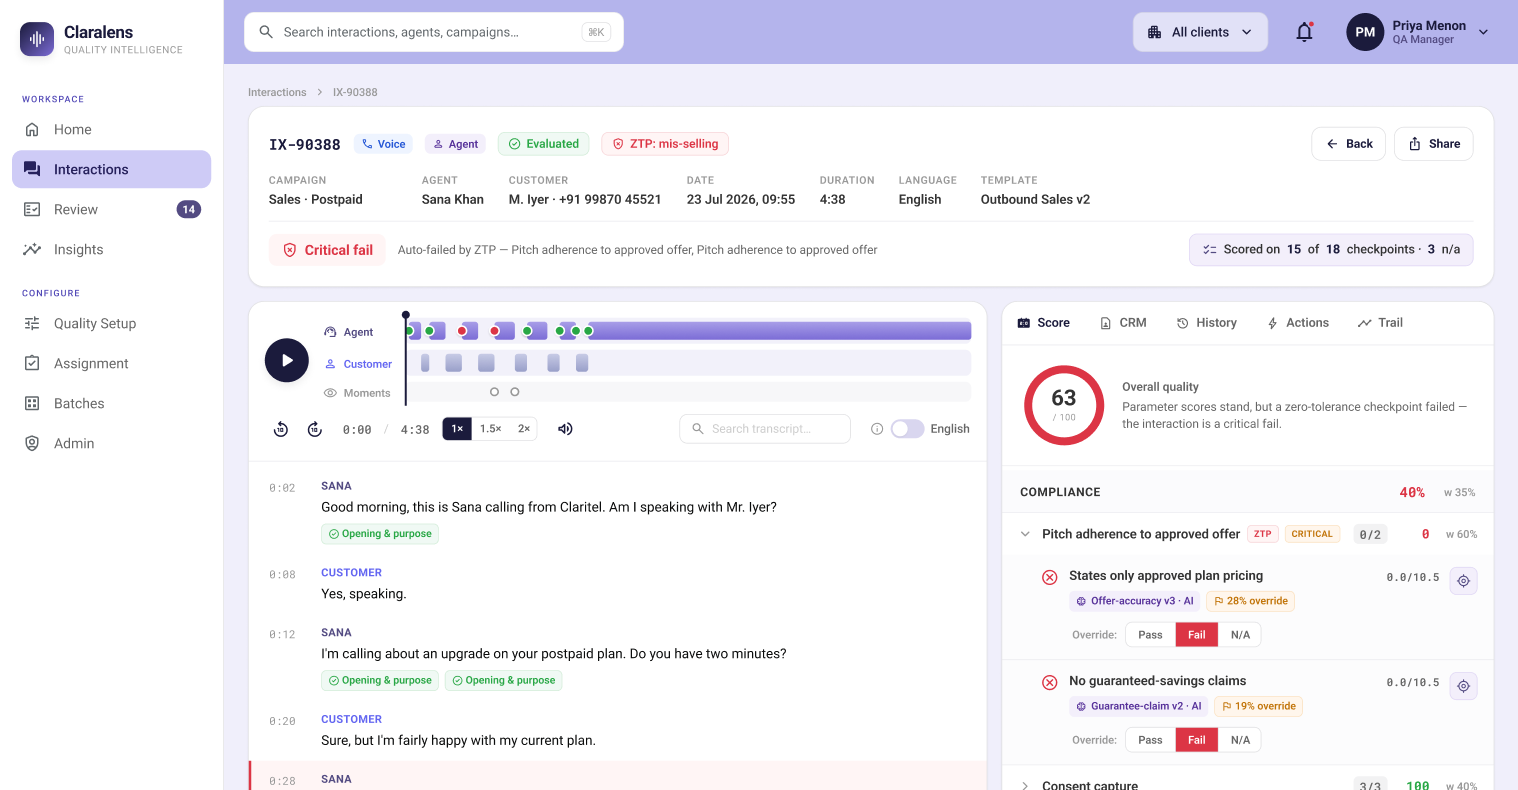
Contact centres in regulated sectors like BFSI and collections need to know whether agents and bots follow script, compliance and policy. Manual QA samples only a small fraction of calls. Claralens audits interactions through a three-level scoring hierarchy (Category → Parameter → Checkpoint). A Detector Library sits underneath it, with rule-based detectors for deterministic checks and instructional (LLM) detectors for judgment calls.
The design problem wasn't really scoring at scale, since every competitor claims that. It was trust. I designed around data honesty: no score appears without its coverage context, N/A is excluded from denominators, every finding links to evidence, and Template Health gates all rankings. The idea behind that last rule is that you can't rank agents until the measuring instrument itself is proven reliable. The analytics layer follows a six-phase lifecycle (Ask → Prepare → Process → Analyze → Share → Act), which works as an inclusion gate for every insight. It is also the first product I know of in this space to put humans and AI bots on dual scorecards.
My role: Product strategy, competitive positioning, information architecture, analytics architecture and insight catalogue, data modelling, UI specs.